Deploying LiteLLM: An Open-Source AI Gateway
Deploy LiteLLM on a Linux server with Docker Compose, PostgreSQL, Prometheus, and Traefik to run an OpenAI-compatible AI gateway.
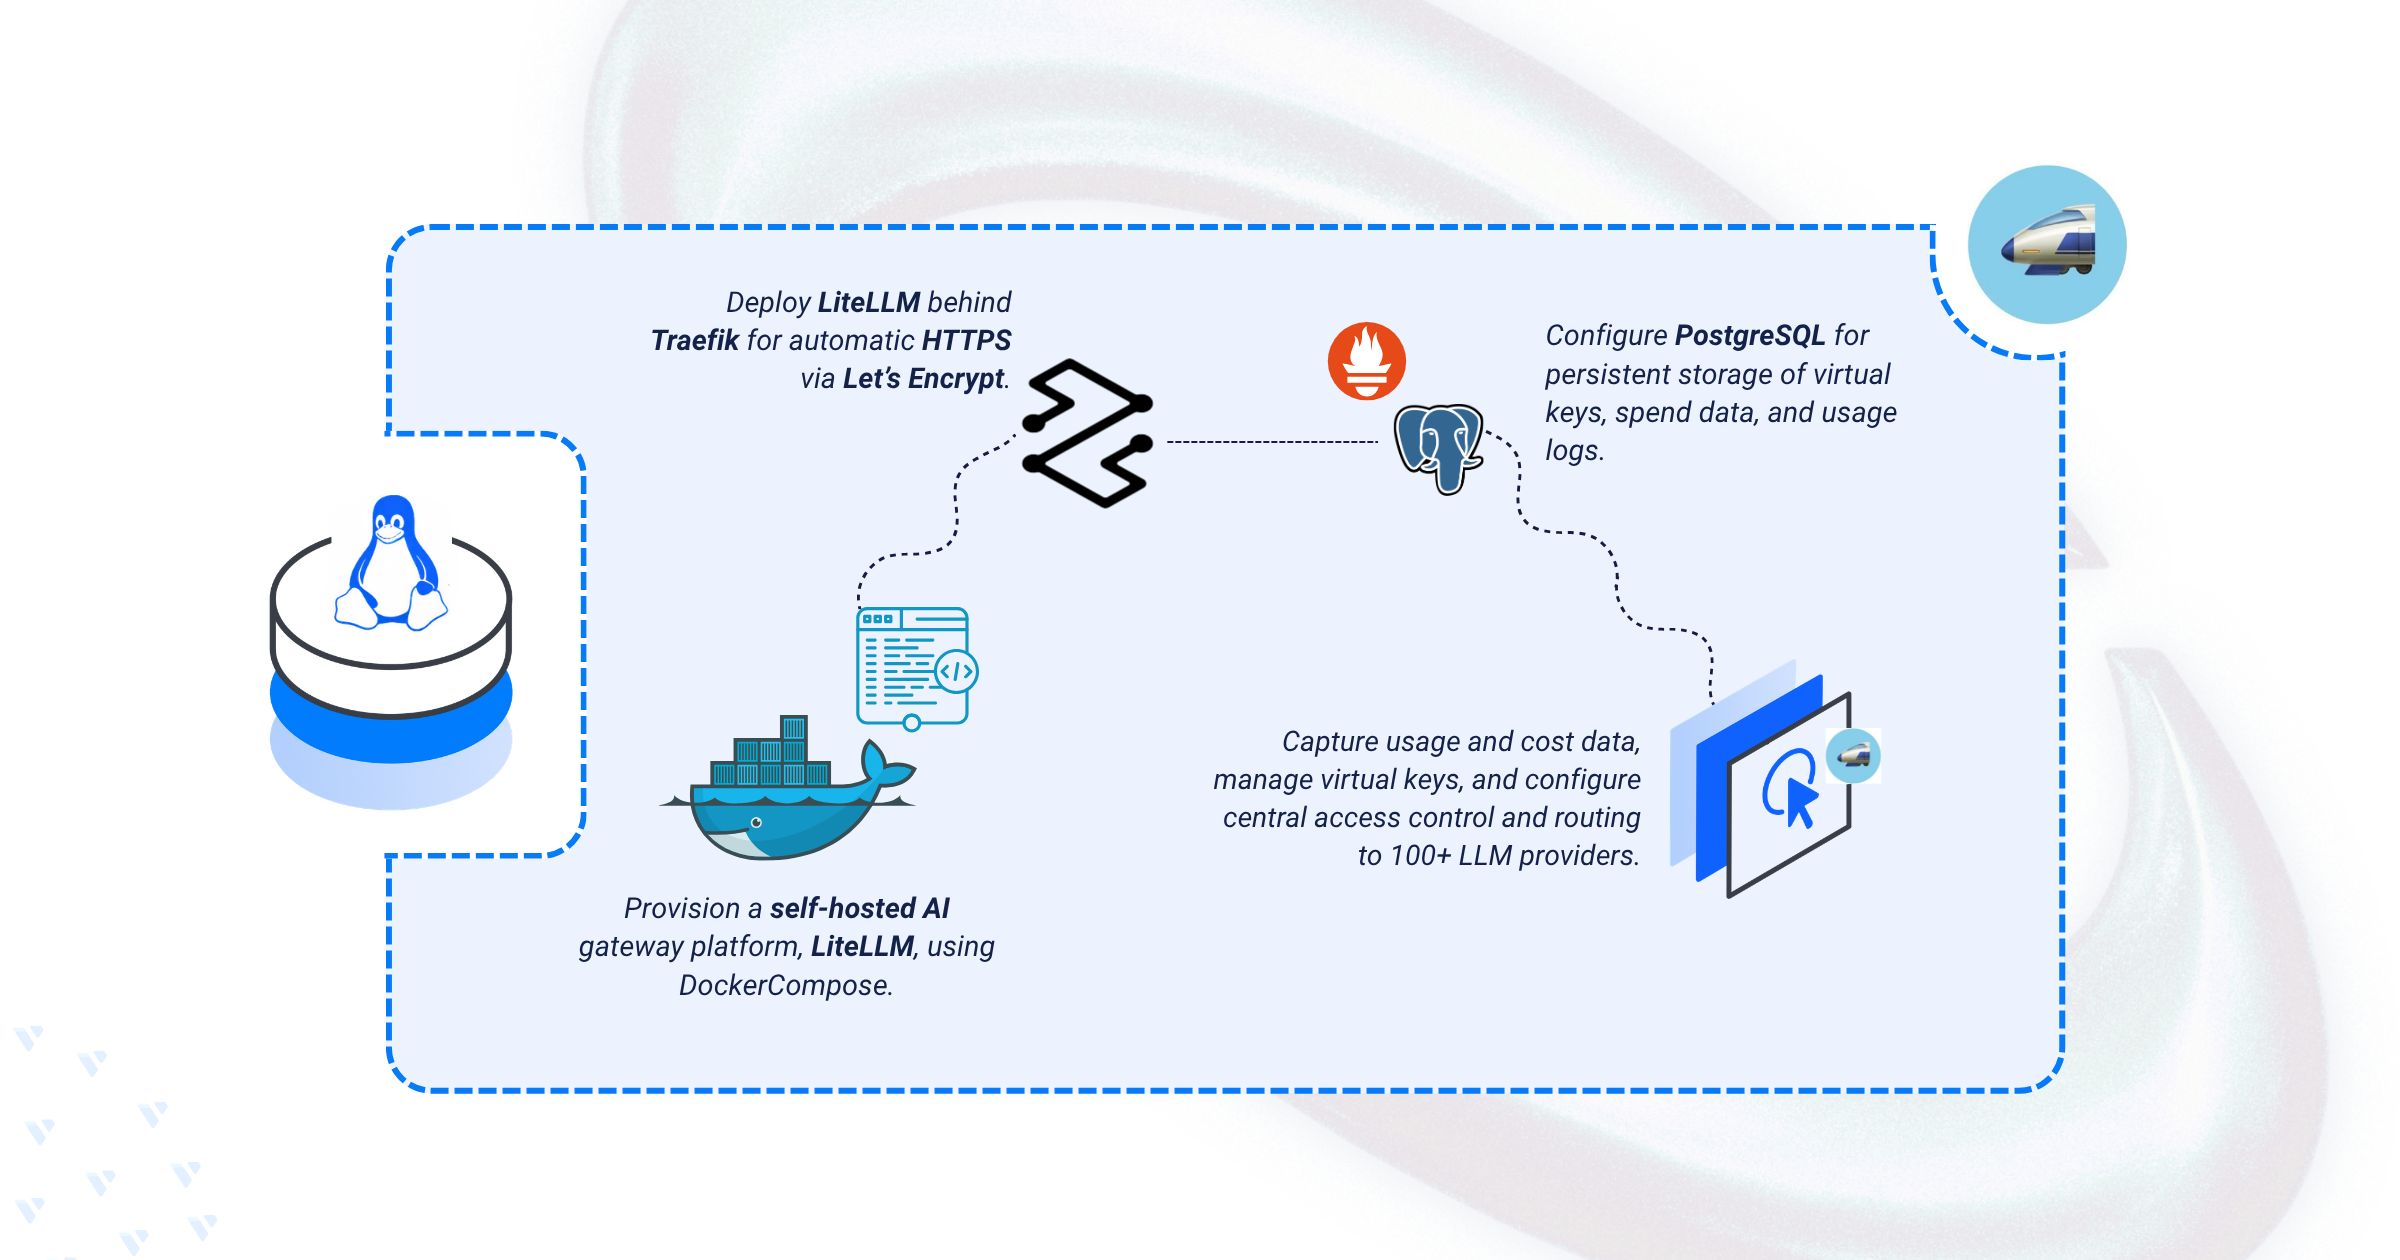
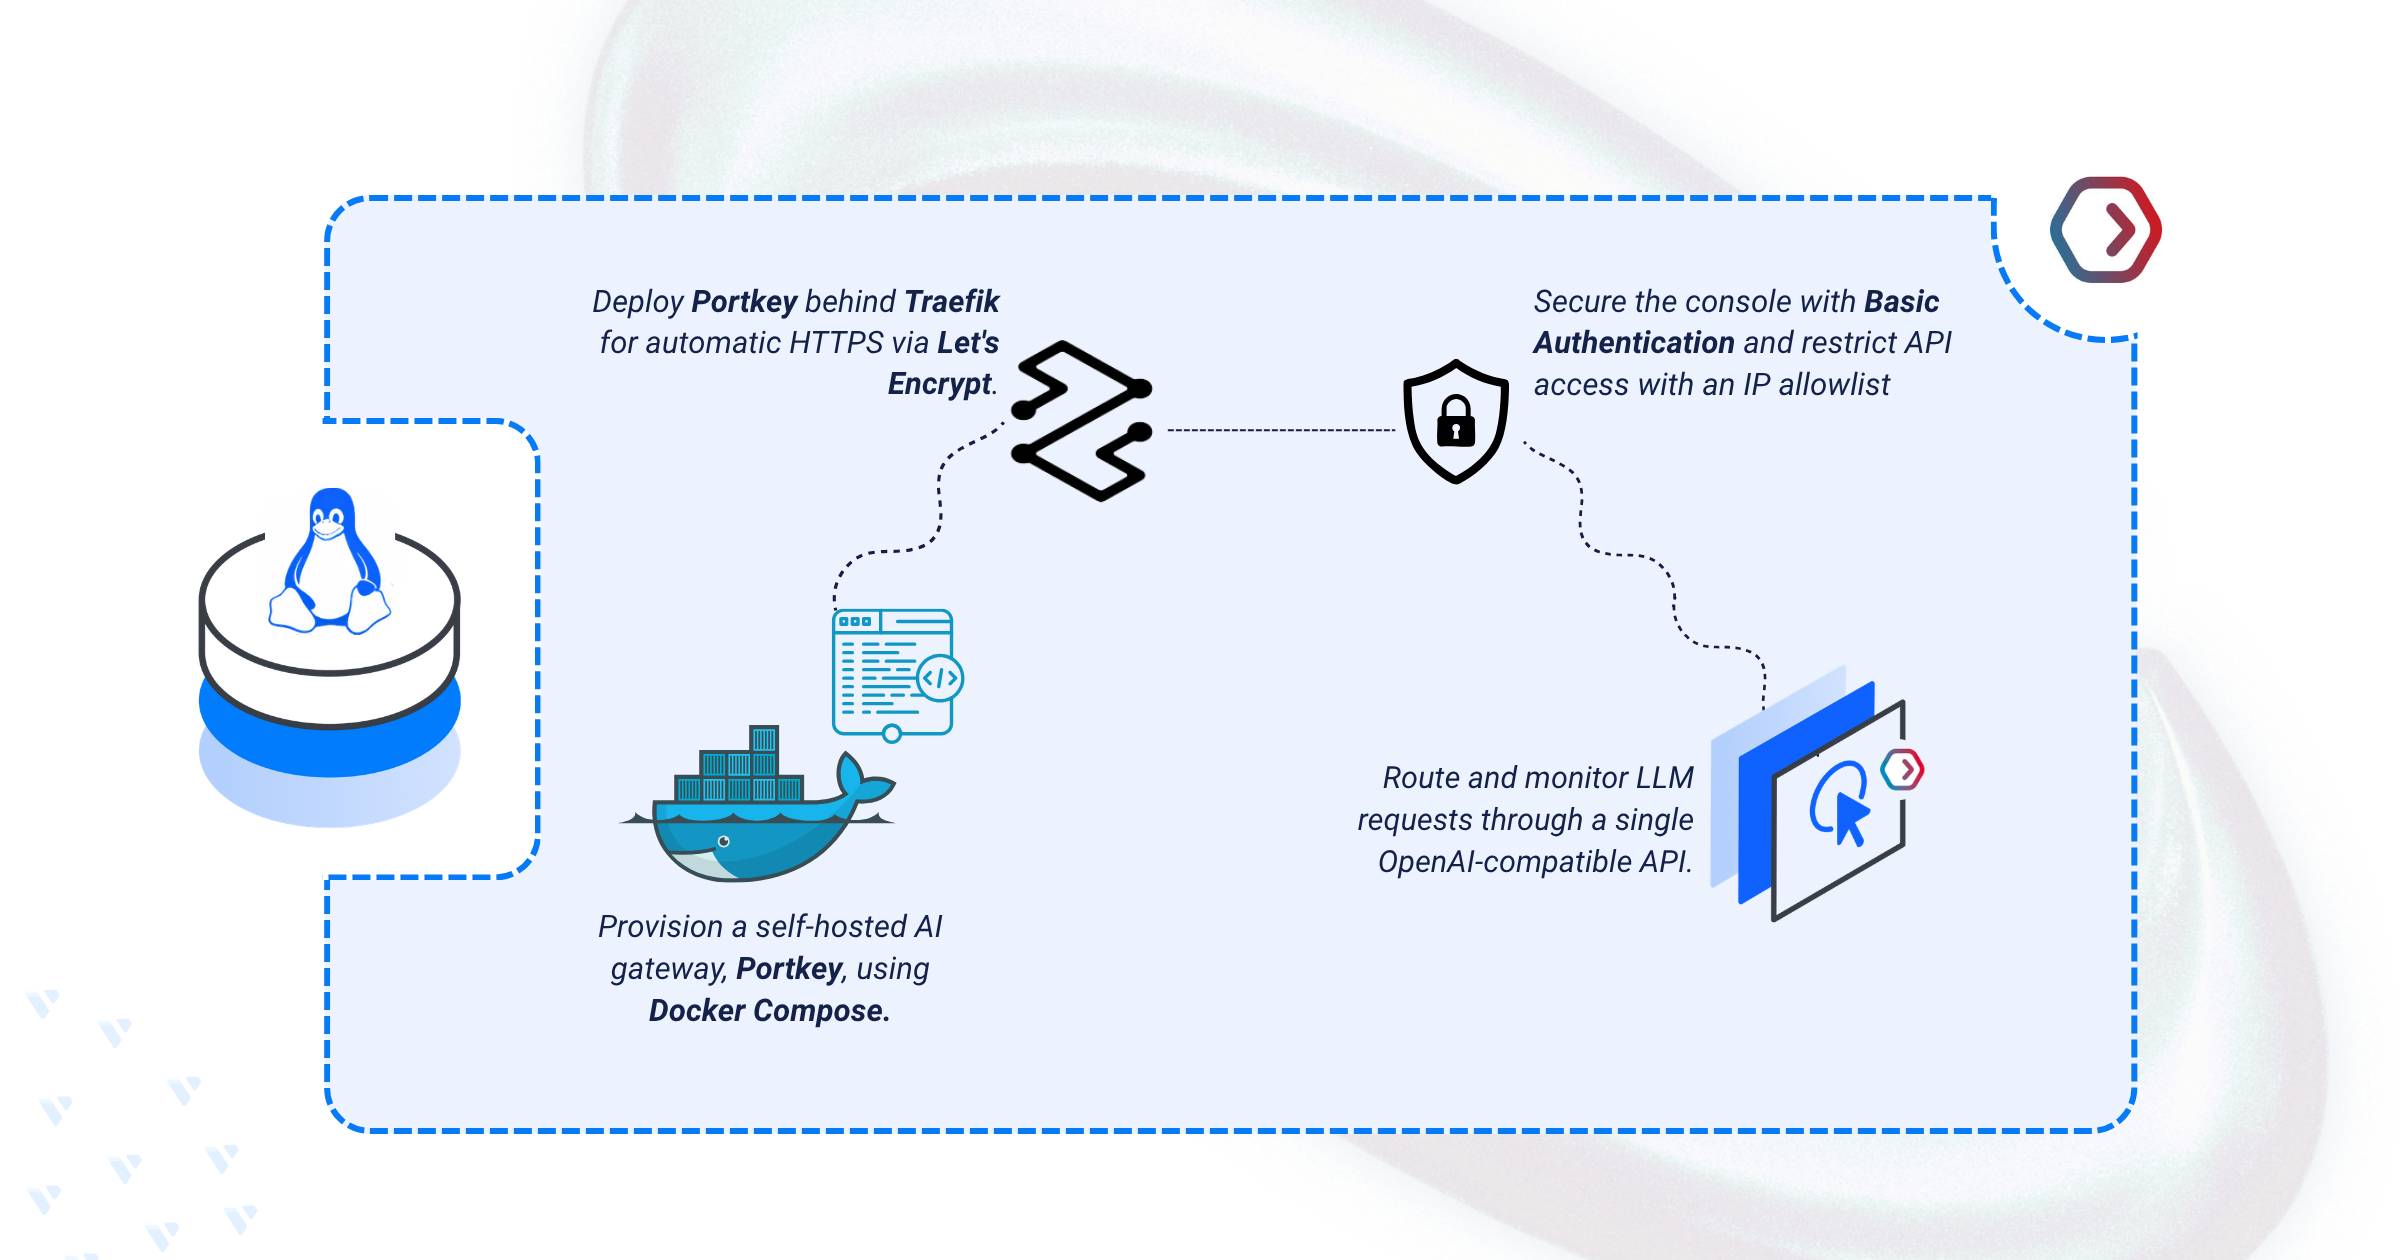
LiteLLM is an open-source AI gateway that provides a unified, OpenAI-compatible API for over 100 large language model (LLM) providers, removing the need to integrate with each provider's SDK and authentication scheme. In production, teams use LiteLLM to issue virtual keys with budget limits, track token usage and spend across providers, and configure centralized access control and routing. This guide walks through deploying LiteLLM on a Linux server using Docker Compose with PostgreSQL for persistent storage, Prometheus for metrics collection, and Traefik as the reverse proxy for HTTPS access. By the end, you'll have a fully functional, OpenAI-compatible AI gateway accessible over a custom domain, with virtual key management, spend tracking, and provider routing configured, following AI gateway deployment practices documented in Vultr Docs.
Before you begin, you need a Linux-based server with at least 4 CPU cores and 8 GB of RAM as a non-root user with sudo privileges, Docker and Docker Compose installed, a DNS A record (such as litellm.example.com) pointing to your server's IP address, and an API key from at least one supported LLM provider.
1. Set Up the Directory Structure, Configuration, and Environment Variables
LiteLLM requires a configuration file to define model providers and routing rules, a Prometheus configuration file for metrics scraping, and environment variables for secrets and database credentials.
1. Create the project directory with subdirectories for persistent data:
mkdir -p ~/litellm/{letsencrypt,postgres,prometheus}
letsencrypt stores SSL/TLS certificates, postgres persists PostgreSQL database files, and prometheus persists Prometheus metrics data.
2. Navigate to the project directory:
cd ~/litellm
3. Set matching ownership on the Prometheus host directory (Prometheus runs as UID 65534 inside the container):
sudo chown -R 65534:65534 prometheus
4. Generate a master key and salt key for LiteLLM. Run this command twice to produce two separate values:
openssl rand -hex 32
Save both values for the LITELLM_MASTER_KEY and LITELLM_SALT_KEY fields in the next step.
5. Create the .env file to store credentials and secrets:
nano .env
6. Add the following values:
DOMAIN=litellm.example.com
LETSENCRYPT_EMAIL=admin@example.com
LITELLM_MASTER_KEY=sk-YOUR_MASTER_KEY
LITELLM_SALT_KEY=sk-YOUR_SALT_KEY
LLM_PROVIDER_API_KEY=YOUR_LLM_PROVIDER_API_KEY
POSTGRES_PASSWORD=STRONG_DATABASE_PASSWORD
DATABASE_URL=postgresql://llmproxy:${POSTGRES_PASSWORD}@db:5432/litellm
UI_USERNAME=admin
UI_PASSWORD=YOUR_UI_PASSWORD
Replace the placeholders with your own values: litellm.example.com is the domain pointing to your server's IP address; admin@example.com is the email address for Let's Encrypt notifications; sk-YOUR_MASTER_KEY is the admin key used to authenticate with the LiteLLM API (replace YOUR_MASTER_KEY with the first generated value and keep the sk- prefix); sk-YOUR_SALT_KEY encrypts provider credentials stored in PostgreSQL and cannot be changed after the first model is added; YOUR_LLM_PROVIDER_API_KEY is the API key for the provider configured in config.yaml; STRONG_DATABASE_PASSWORD is the PostgreSQL password used by both the database container and the connection string; admin/YOUR_UI_PASSWORD are the LiteLLM dashboard credentials.
7. Create the LiteLLM configuration file:
nano config.yaml
8. Add the following contents:
model_list:
  - model_name: my-model
    litellm_params:
      model: provider/model
      api_key: os.environ/LLM_PROVIDER_API_KEY

litellm_settings:
  callbacks:
    - prometheus
  require_auth_for_metrics_endpoint: true

general_settings:
  master_key: os.environ/LITELLM_MASTER_KEY
Replace my-model with a name of your choice to identify this model within LiteLLM, and provider/model with the LiteLLM provider prefix followed by the model identifier (for example, anthropic/claude-haiku-4-5). The os.environ/ prefix tells LiteLLM to read the value from an environment variable at runtime rather than hardcoding it. The litellm_settings block enables Prometheus metrics via the callbacks field, and require_auth_for_metrics_endpoint: true restricts the /metrics endpoint to authenticated requests, so only Prometheus (sending the master key as a Bearer token) can scrape metrics successfully. The general_settings block defines the master key LiteLLM uses to authenticate admin API requests and virtual key management operations.
9. Create the Prometheus configuration file:
nano prometheus.yml
10. Add the following contents:
global:
  scrape_interval: 15s
  evaluation_interval: 15s

scrape_configs:
  - job_name: "litellm"
    static_configs:
      - targets: ["litellm:4000"]
    bearer_token: "sk-YOUR_MASTER_KEY"
Replace sk-YOUR_MASTER_KEY with the value of LITELLM_MASTER_KEY from your .env file. Prometheus uses this token to authenticate its scrape requests against the protected /metrics endpoint.
2. Deploy with Docker Compose
The deployment stack runs LiteLLM behind Traefik, which handles TLS termination and automatic certificate provisioning through Let's Encrypt. PostgreSQL provides persistent storage for virtual keys, spend data, and usage logs. Prometheus collects gateway metrics by scraping the LiteLLM /metrics endpoint every 15 seconds over the internal Docker network.
1. Add your user account to the Docker group:
sudo usermod -aG docker $USER
2. Apply the new group membership:
newgrp docker
3. Create the Docker Compose manifest file:
nano docker-compose.yaml
4. Add the following contents:
services:
  traefik:
    image: traefik:v3.6
    container_name: traefik
    restart: always
    command:
      - "--providers.docker=true"
      - "--providers.docker.exposedbydefault=false"
      - "--entrypoints.web.address=:80"
      - "--entrypoints.websecure.address=:443"
      - "--entrypoints.web.http.redirections.entrypoint.to=websecure"
      - "--entrypoints.web.http.redirections.entrypoint.scheme=https"
      - "--certificatesresolvers.le.acme.httpchallenge=true"
      - "--certificatesresolvers.le.acme.httpchallenge.entrypoint=web"
      - "--certificatesresolvers.le.acme.email=${LETSENCRYPT_EMAIL}"
      - "--certificatesresolvers.le.acme.storage=/letsencrypt/acme.json"
    ports:
      - "80:80"
      - "443:443"
    volumes:
      - /var/run/docker.sock:/var/run/docker.sock:ro
      - ./letsencrypt:/letsencrypt

  litellm:
    image: docker.litellm.ai/berriai/litellm:v1.89.1
    container_name: litellm
    restart: always
    volumes:
      - ./config.yaml:/app/config.yaml
    command:
      - "--config=/app/config.yaml"
    environment:
      DATABASE_URL: ${DATABASE_URL}
      STORE_MODEL_IN_DB: "True"
    env_file:
      - .env
    expose:
      - "4000"
    depends_on:
      db:
        condition: service_healthy
    healthcheck:
      test:
        - CMD-SHELL
        - python3 -c "import urllib.request; urllib.request.urlopen('http://localhost:4000/health/liveliness')"
      interval: 30s
      timeout: 10s
      retries: 3
      start_period: 40s
    labels:
      - "traefik.enable=true"
      - "traefik.http.routers.litellm.rule=Host(`${DOMAIN}`)"
      - "traefik.http.routers.litellm.entrypoints=websecure"
      - "traefik.http.routers.litellm.tls=true"
      - "traefik.http.routers.litellm.tls.certresolver=le"
      - "traefik.http.services.litellm.loadbalancer.server.port=4000"

  db:
    image: postgres:16
    container_name: litellm_db
    restart: always
    environment:
      POSTGRES_DB: litellm
      POSTGRES_USER: llmproxy
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
    volumes:
      - ./postgres:/var/lib/postgresql/data
    expose:
      - "5432"
    healthcheck:
      test: ["CMD-SHELL", "pg_isready -d litellm -U llmproxy"]
      interval: 1s
      timeout: 5s
      retries: 10

  prometheus:
    image: prom/prometheus
    container_name: litellm_prometheus
    restart: always
    volumes:
      - ./prometheus:/prometheus
      - ./prometheus.yml:/etc/prometheus/prometheus.yml
    expose:
      - "9090"
    command:
      - "--config.file=/etc/prometheus/prometheus.yml"
      - "--storage.tsdb.path=/prometheus"
      - "--storage.tsdb.retention.time=15d"
This configuration deploys four services behind a single HTTPS endpoint: traefik acts as the reverse proxy and TLS terminator, redirecting HTTP to HTTPS via Let's Encrypt; litellm runs the proxy image pinned to a specific release tag, mounts config.yaml, and waits for PostgreSQL to become healthy before starting; db runs PostgreSQL 16 as the persistent backend for virtual keys, spend data, and usage logs; prometheus scrapes LiteLLM metrics every 15 seconds with a 15-day retention window. The named volumes for db and prometheus ensure their data survives container removal or recreation.
Verify the Docker Image with Cosign
LiteLLM Docker images are signed with Cosign. Verifying the image signature before deployment confirms the image has not been tampered with since it was published by the LiteLLM team.
1. Download and install the Cosign binary:
curl -O -L "https://github.com/sigstore/cosign/releases/latest/download/cosign-linux-amd64"
2. Move the binary into your system path:
sudo mv cosign-linux-amd64 /usr/local/bin/cosign
3. Make the binary executable:
sudo chmod +x /usr/local/bin/cosign
4. Verify the installation:
cosign version
5. Verify the LiteLLM image signature using the pinned public key. This checks the same release tag deployed in the Docker Compose file. LiteLLM publishes signatures for the ghcr.io registry specifically, so this confirms the v1.89.1 release itself, not the docker.litellm.ai mirror byte-for-byte.
cosign verify \
    --key https://raw.githubusercontent.com/BerriAI/litellm/0112e53046018d726492c814b3644b7d376029d0/cosign.pub \
    ghcr.io/berriai/litellm:v1.89.1
A successful verification outputs a JSON payload confirming the image was signed with the LiteLLM public key.
Start the Stack
1. Start the services:
docker compose up -d
2. Verify all containers are running:
docker compose ps
Verify that all four containers show an Up status, with litellm and db marked (healthy) and traefik listing ports 80 and 443 under PORTS.
3. Access and Configure LiteLLM
LiteLLM exposes a web-based admin dashboard at the /ui path of your configured domain, with visibility into model configuration, virtual keys, usage, and spend tracking.
Open your web browser and navigate to
https://litellm.example.com/ui, replacinglitellm.example.comwith your configured domain.Log in using the credentials from your
.envfile — the value ofUI_USERNAMEin the Username field andUI_PASSWORDin the Password field, then click Login. Verify that the dashboard loads and displays the main navigation panels.Click Models + Endpoints in the left sidebar to verify the configured model providers. The model defined in
config.yamlappears in the list with its alias and underlying provider model. The left sidebar also provides access to Virtual Keys for managing scoped access credentials, Usage for per-model and per-key request tracking, and Logs for spend and cost breakdowns by model, key, and team.
4. Test the Gateway and Create a Virtual Key
LiteLLM exposes an OpenAI-compatible API, so any application built for the OpenAI SDK works with LiteLLM by pointing base_url at the gateway. Virtual keys provide scoped, credential-isolated access without exposing the master key.
1. Install the Python virtual environment package:
sudo apt install -y python3-venv
2. Create a Python virtual environment:
python3 -m venv litellm-env
3. Activate the virtual environment:
source litellm-env/bin/activate
4. Install the OpenAI Python SDK:
pip install openai
5. Export your master key as an environment variable, replacing sk-YOUR_MASTER_KEY with the LITELLM_MASTER_KEY value from your .env file:
export LITELLM_MASTER_KEY="sk-YOUR_MASTER_KEY"
6. Export your gateway domain as an environment variable, replacing litellm.example.com with your configured domain:
export LITELLM_DOMAIN="litellm.example.com"
7. Create the test script:
nano test_litellm.py
8. Add the following contents, replacing my-model with the model name you set in config.yaml:
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["LITELLM_MASTER_KEY"],
    base_url=f"https://{os.environ['LITELLM_DOMAIN']}",
)

response = client.chat.completions.create(
    model="my-model",
    messages=[{"role": "user", "content": "What is an AI gateway?"}],
)

print(response.choices[0].message.content)
9. Run the script:
python3 test_litellm.py
The script returns a response from the configured LLM provider, confirming the gateway is routing requests correctly.
10. Create a virtual key using the LiteLLM API, replacing my-model with the model name you set in config.yaml:
curl -X POST "https://${LITELLM_DOMAIN}/key/generate" \
    -H "Authorization: Bearer ${LITELLM_MASTER_KEY}" \
    -H "Content-Type: application/json" \
    -d '{"key_alias": "test-app-key", "models": ["my-model"], "max_budget": 5.00}' \
    | python3 -c "import sys, json; print(json.load(sys.stdin)['key'])"
The command prints the generated virtual key, similar to sk-M9M0_aUDLi7AuhXtOAw6uw. Each key can have its own model access list, budget limit, and rate limit.
11. Export the virtual key returned in the previous step, replacing sk-your-virtual-key with the full key string printed:
export LITELLM_VIRTUAL_KEY="sk-your-virtual-key"
12. Send a request using the virtual key, replacing my-model with the model name you set in config.yaml:
curl -X POST "https://${LITELLM_DOMAIN}/v1/chat/completions" \
    -H "Authorization: Bearer ${LITELLM_VIRTUAL_KEY}" \
    -H "Content-Type: application/json" \
    -d '{
      "model": "my-model",
      "messages": [{"role": "user", "content": "Hello from a virtual key!"}]
    }'
The gateway authenticates the virtual key, routes the request to the configured provider, and returns the model response.
13. Return to the dashboard at https://litellm.example.com/ui and click Logs in the left sidebar. Each entry shows the model alias, key alias, token count, and estimated cost for requests sent through both the master key and the virtual key.
Next Steps
Add more models to
config.yamland issue per-team or per-application virtual keys with distinct budget limits.Build Grafana dashboards on top of the Prometheus metrics for gateway observability.
Set up alerting on budget thresholds and failed provider requests.
Rotate the master key and salt key periodically and re-verify Docker image signatures on every upgrade.
For the full guide with additional tips, visit the original article on Vultr Docs.