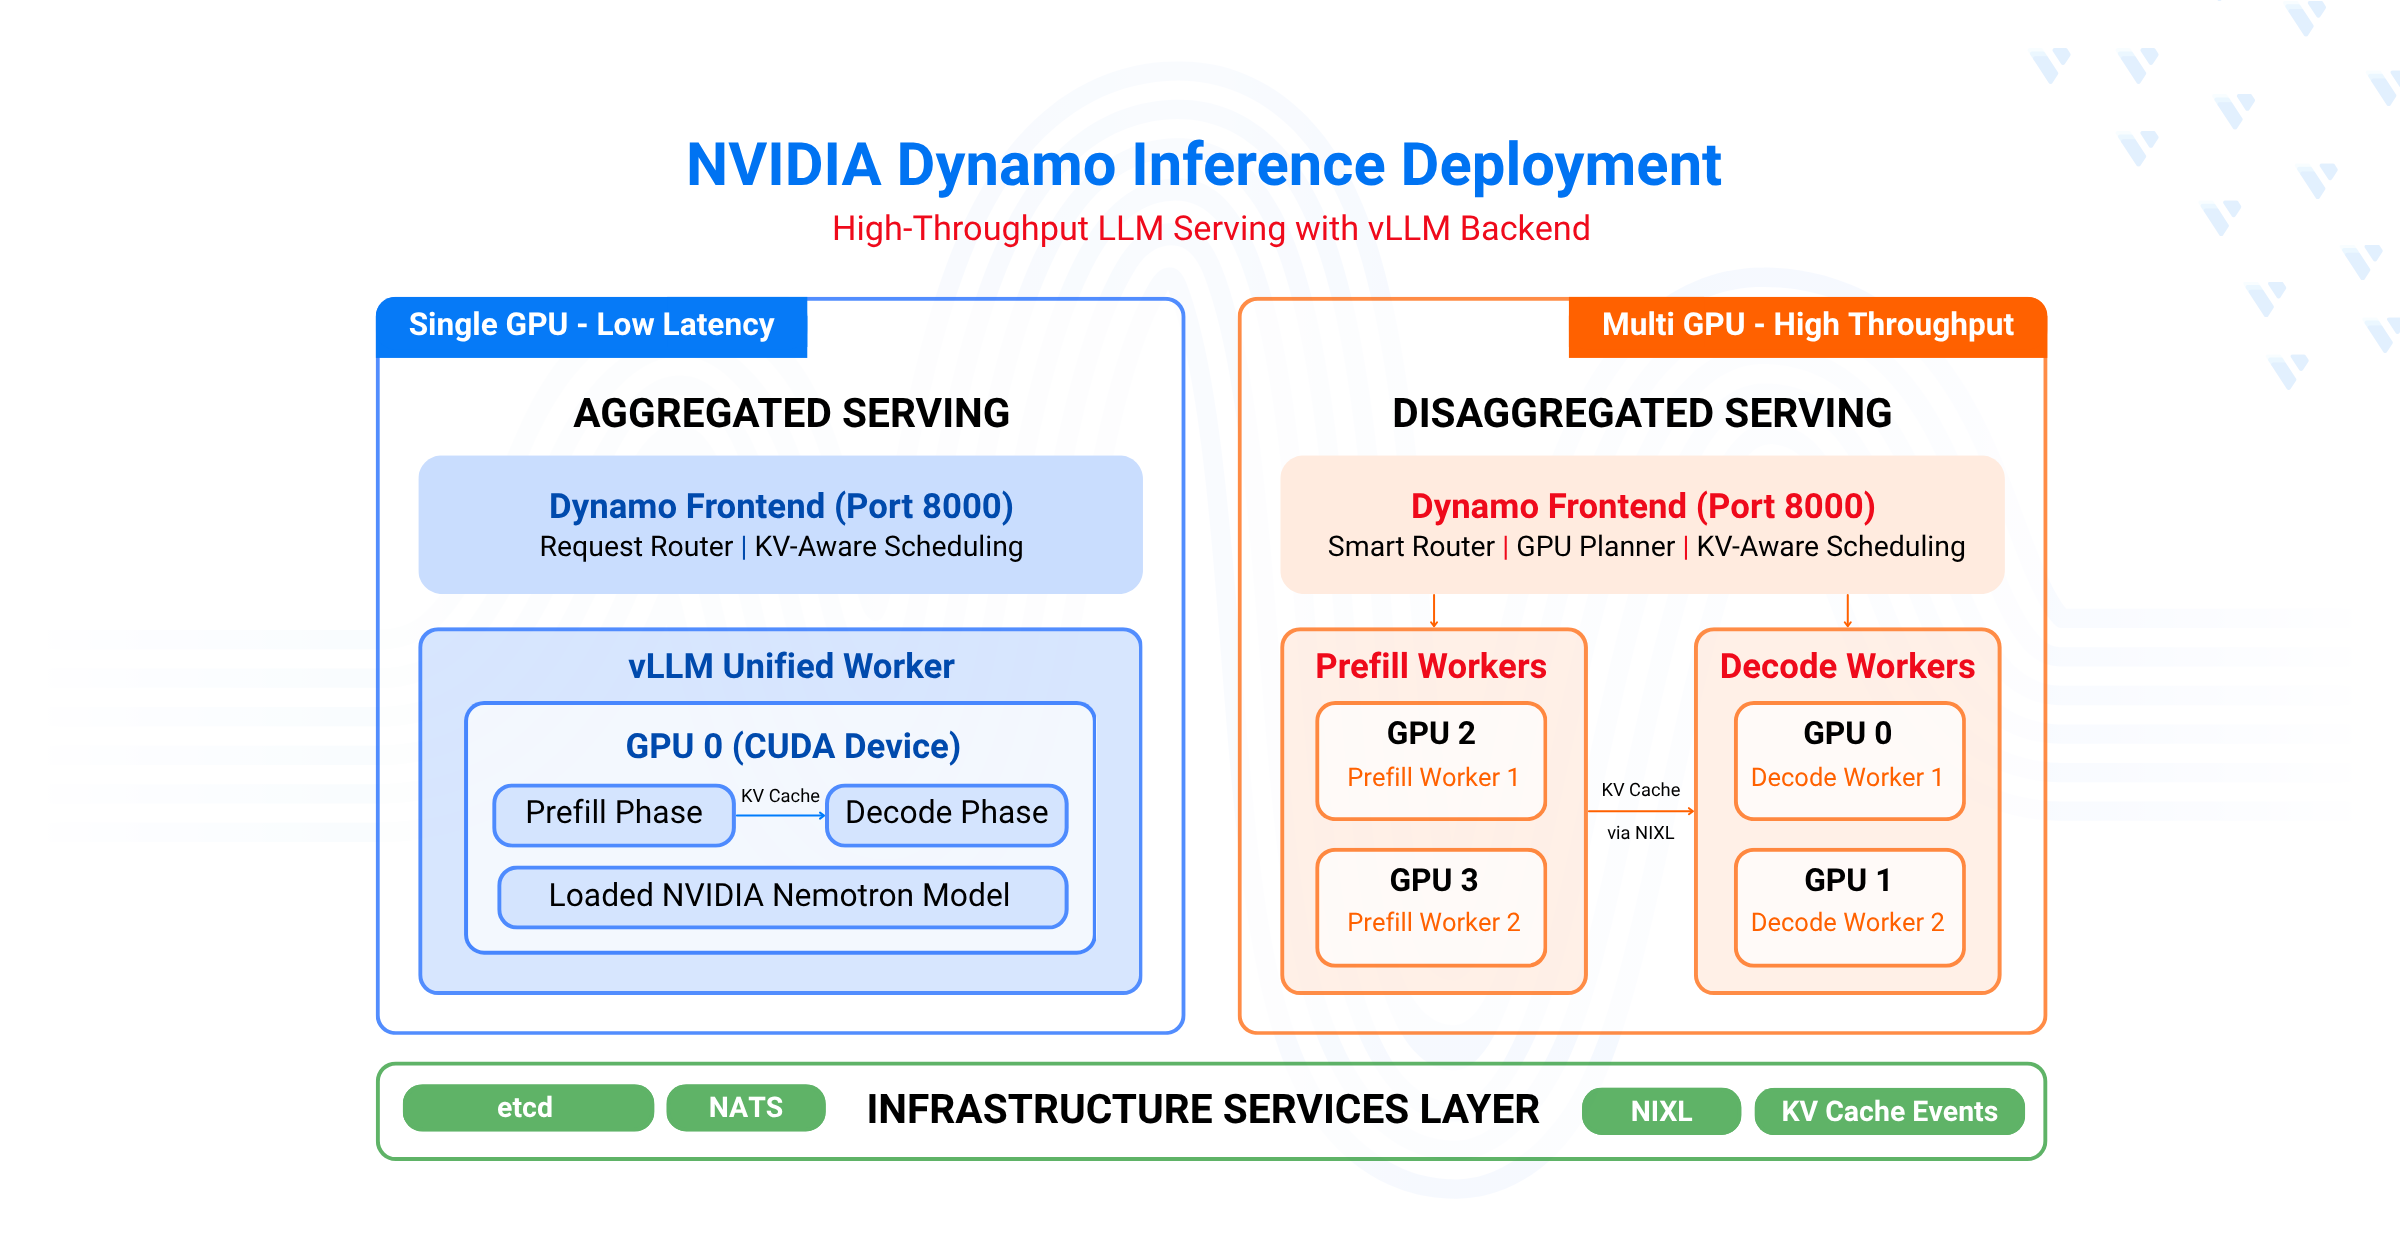
Deploying Inference Using NVIDIA Dynamo and vLLMDeploy NVIDIA Dynamo with vLLM for high-throughput, low-latency LLM inference using aggregated and disaggregated GPU serving.Sep 3, 2026·9 min read